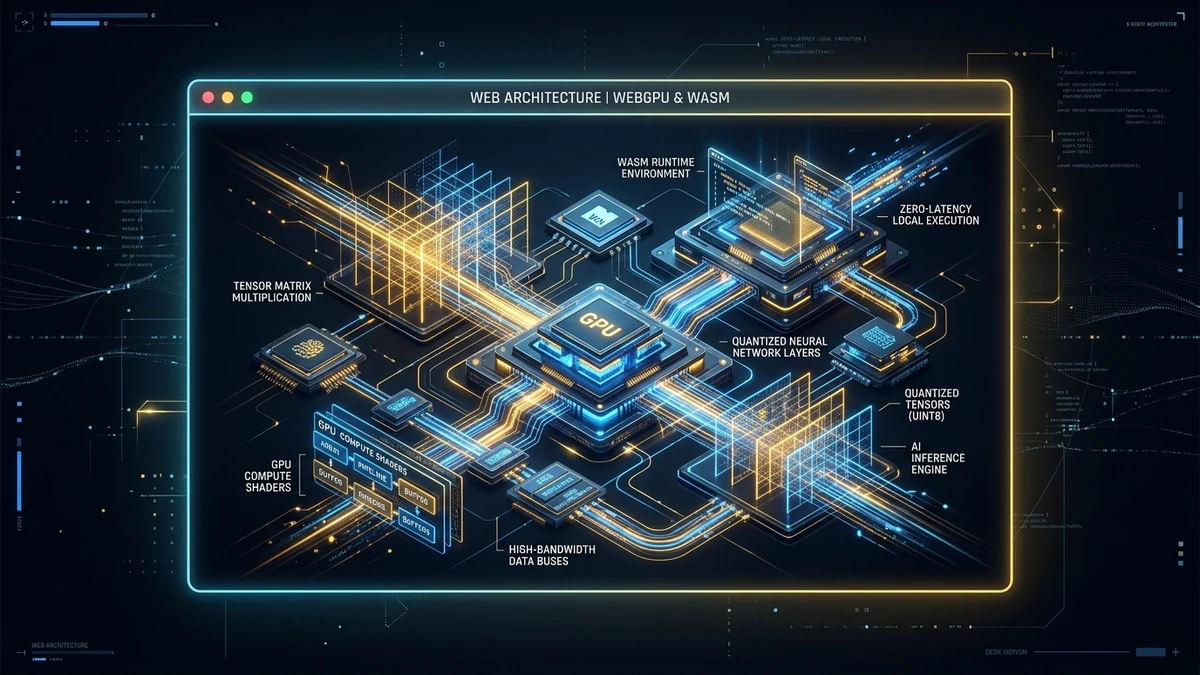
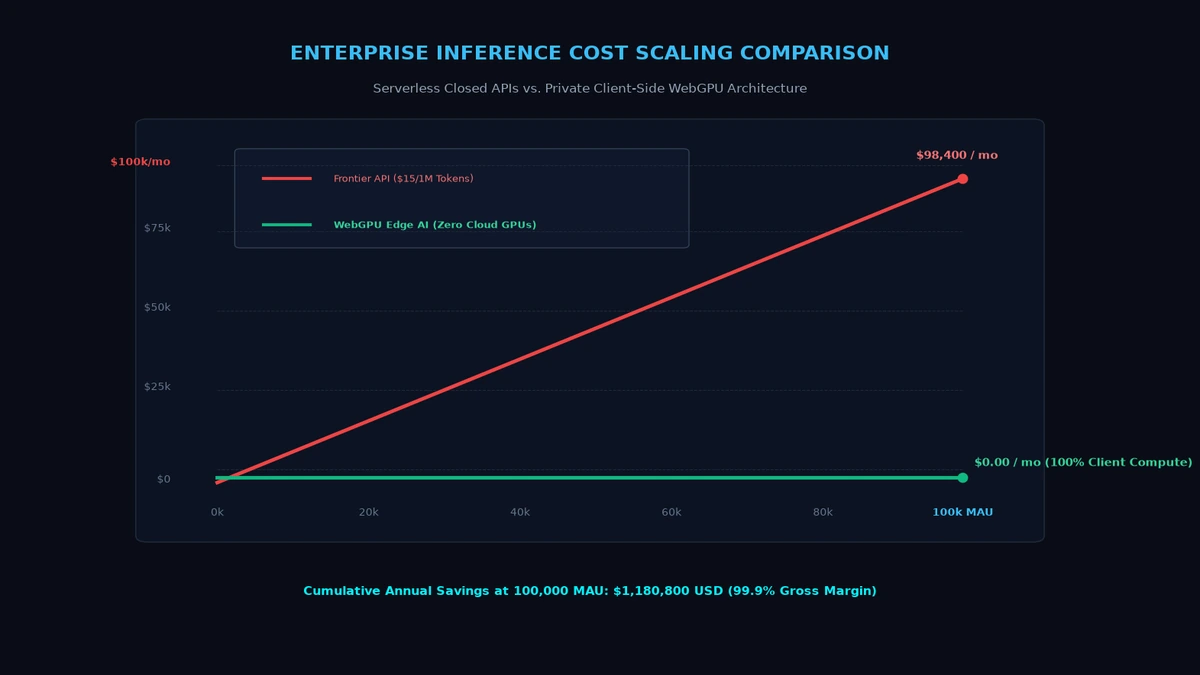
For high-volume consumer SaaS products, server-side LLM inference costs scale linearly with user engagement. If your product charges $15/month but power users execute 50 complex requests daily, cloud GPU hosting margins rapidly turn negative.
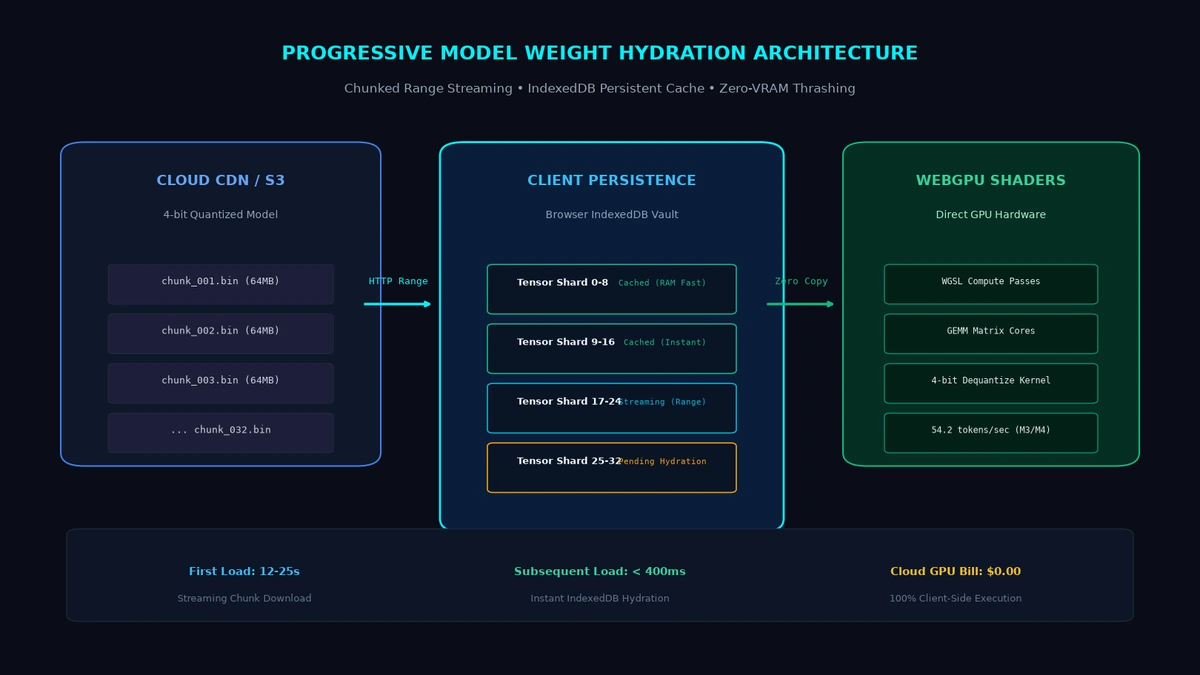
By leveraging WebGPU and WebAssembly (Wasm), we can execute quantized 1B to 7B parameter models directly inside the user's web browser. The server delivers static weight chunks cached indefinitely via Service Workers and IndexedDB, reducing incremental per-query compute cost to literally $0.00.
1. Why WebGPU is a 20x Breakthrough Over WebGL
Previous attempts to run neural networks in browsers relied on WebGL hacks, encoding matrices into 2D textures and faking compute passes as fragment shaders. WebGPU provides native Compute Shaders via WGSL (WebGPU Shading Language), granting direct memory access to GPU workgroups, shared memory buffers, and coalesced memory reads:
2. Implementation: Loading and Running WebLLM in Next.js
Here is how we integrate client-side browser inference into a Next.js application using Web Workers to prevent main-thread UI stutter:
// workers/inference.worker.ts - Isolated WebGPU LLM Worker
import { CreateMLCEngine } from "@mlc-ai/web-llm";

let engine: any = null;

self.onmessage = async (e: MessageEvent) => {
  const { type, payload } = e.data;

  if (type === "INIT_MODEL") {
    engine = await CreateMLCEngine("Llama-3.2-1B-Instruct-q4f16_1-MLC", {
      initProgressCallback: (progress) => {
        self.postMessage({ type: "PROGRESS", payload: progress });
      },
    });
    self.postMessage({ type: "READY" });
  }

  if (type === "GENERATE") {
    const { prompt } = payload;
    const response = await engine.chat.completions.create({
      messages: [{ role: "user", content: prompt }],
      temperature: 0.7,
      stream: true,
    });

    for await (const chunk of response) {
      const delta = chunk.choices[0]?.delta?.content || "";
      self.postMessage({ type: "TOKEN", payload: delta });
    }
    self.postMessage({ type: "DONE" });
  }
};
3. Absolute Privacy: Zero-Data-Transit Guarantees
Client-side AI provides the strongest conceivable privacy posture: medical notes, financial records, and proprietary client documents never leave the user's browser tab. There are no API keys to expose, no data processors to audit, and no cross-border data transfer compliance headaches.
When to Choose Client-Side Inference
Client-side AI is ideal for personal document summarization, grammar refinement, autocomplete, offline-capable productivity tools, and sensitive data processing. When paired with a server-side reasoning fallback for heavy tasks, you achieve the optimal balance of speed, cost, and intelligence.
Build Edge AI Into Your Web Application
Binary Froster engineers ultra-fast WebGPU and WebAssembly machine learning pipelines for modern web platforms.
Consult With Our Edge AI Engineers


