Building a single LLM prompt into an API endpoint is trivial. Orchestrating a constellation of 10 to 50 autonomous agents that communicate over asynchronous message buses, execute external tools, negotiate consensus, and self-heal when a model hallucinates or an upstream tool fails is one of the most challenging distributed systems problems in modern software engineering.
At Binary Froster, we transitioned our enterprise agent infrastructure from single-agent monolithic prompt chains to a decoupled, event-driven multi-agent mesh. This architecture eliminates infinite agent loops, caps token burn through strict context budgeting, and provides mathematical guarantees against cascading tool failures.
1. Multi-Agent Topologies: Why Hierarchical Trees Dominate Mesh Networks
When engineers first construct multi-agent systems, the instinct is often to build a peer-to-peer (P2P) mesh where any agent can send messages to any other agent. In production, unconstrained P2P topologies rapidly collapse under O(N²) communication complexity, leading to conversational deadlocks, repetitive debates, and runaway LLM token bills.
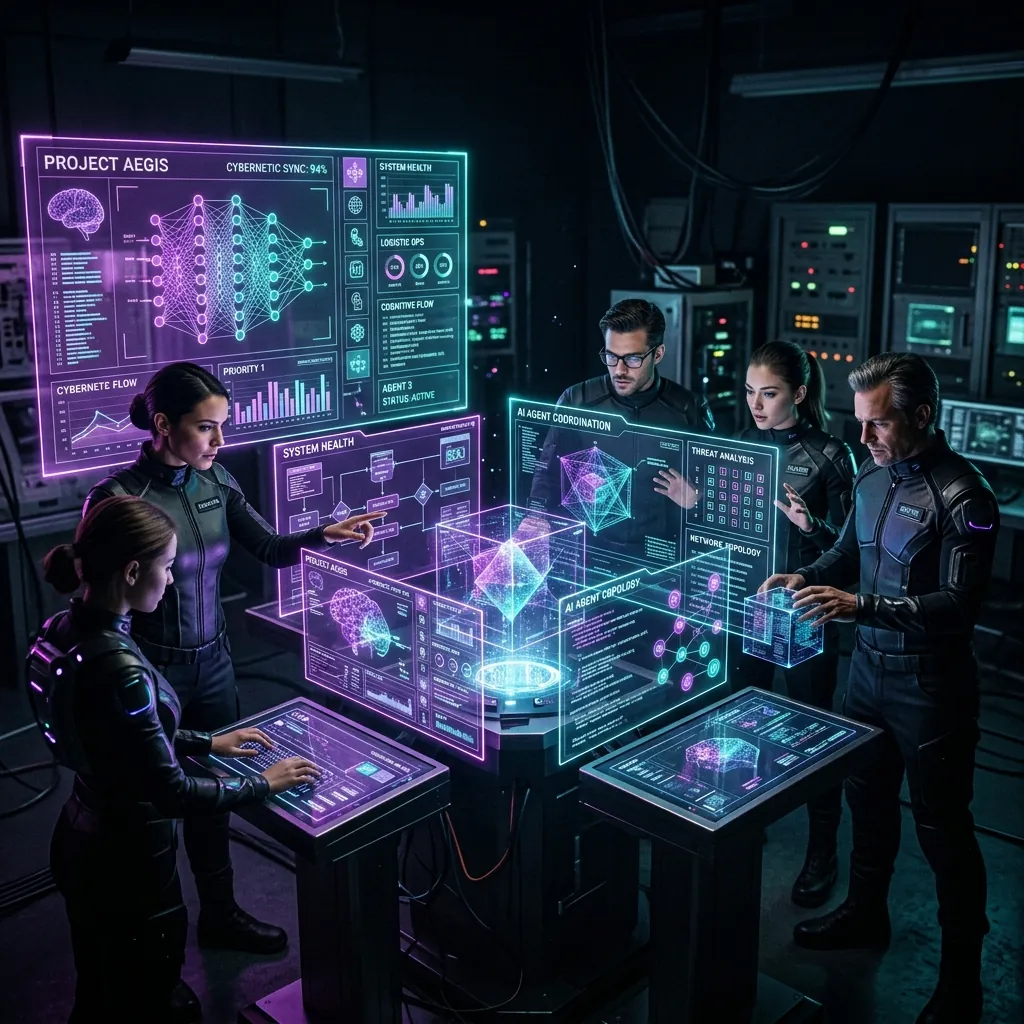
For mission-critical production systems, we enforce a Hierarchical Supervisor-Worker Topology with an isolated Blackboard Memory Store:
- Supervisor / Router Agent: Owns the global task state machine. Breaks down ambiguous client intents into a Directed Acyclic Graph (DAG) of discrete tasks, assigns priorities, and evaluates final completion criteria. Never executes heavy tool calls directly.
- Domain Specialist Workers: Sandboxed agents equipped with narrow, idempotent tool sets (e.g., SQL Data Miner, Static Code Analyzer, Threat Modeler). Workers only communicate with the Supervisor or push structured output artifacts to the Blackboard.
- Critic / Evaluator Agent: Independent verification agent running adversarial prompts to stress-test outputs before customer-facing delivery.
2. The Context Window Budgeting Algorithm
Even with 1M+ context window LLMs, dumping entire conversational histories into each agent invocation destroys latency, incurs extreme API billing, and introduces "needle in a haystack" attention degradation. We enforce strict Context Budgets per agent cycle:
When an agent's reasoning scratchpad approaches 80% of its allocation, a lightweight background summarizer compresses prior steps into an episodic milestone entry, preventing context blowup while preserving key constraints and intermediate tool returns.
3. Production Circuit Breakers & Dead-Letter Queues
What happens when an external third-party API rate-limits your agent, or a code execution sandbox times out? Without deterministic fault isolation, the agent will repeatedly regenerate the failing tool call until token exhaustion.
We implement distributed circuit breakers using Redis. Here is an architectural pattern implemented in our TypeScript orchestration runtime:
interface AgentCircuitBreaker {
  failureThreshold: number; // e.g. 3 consecutive failures
  cooldownPeriodMs: number;  // 30 seconds before half-open state
  fallbackStrategy: 'ESCALATE_TO_SUPERVISOR' | 'DEGRADE_GRACEFULLY' | 'HUMAN_APPROVAL';
}

export async function executeAgentToolCall(
  agentId: string,
  toolName: string,
  args: Record<string, unknown>
): Promise<ToolExecutionResult> {
  const breakerKey = `circuit:${agentId}:${toolName}`;
  const state = await redis.get(breakerKey);

  if (state === 'OPEN') {
    // Prevent catastrophic tool loop - return synthetic deterministic error to agent
    return {
      status: 'CIRCUIT_OPEN',
      error: `Tool ${toolName} is temporarily paused due to upstream latency. Use alternative approach or request supervisor assistance.`,
      retryAfterSeconds: 30
    };
  }

  try {
    const result = await timeoutPromise(runTool(toolName, args), 12000);
    await redis.del(`failures:${agentId}:${toolName}`);
    return { status: 'SUCCESS', data: result };
  } catch (err) {
    const failures = await redis.incr(`failures:${agentId}:${toolName}`);
    if (failures >= 3) {
      await redis.setex(breakerKey, 30, 'OPEN');
      await logToDeadLetterQueue({ agentId, toolName, args, error: err });
    }
    throw err;
  }
}
4. Observability: OpenTelemetry Tracing for Agentic Workflows
Debugging a chain of 40 asynchronous agent calls requires tracing every tool call, reasoning step, token count, and latency slice. By standardizing on OpenTelemetry spans, our engineering dashboard surfaces the complete dependency graph of every autonomous workflow in real time.
Key Takeaways for System Designers
- Enforce hierarchical topologies: Ban unconstrained P2P chat; make a supervisor agent solely responsible for state machine progression.
- Isolate tools by domain: Provide agents with minimal viable API surfaces to eliminate prompt confusion and unintended side effects.
- Hardware-backed circuit breakers: Treat agent tool invocations like unreliable microservice RPCs with rate limits, timeouts, and dead-letter queues.
- Continuous evaluation gates: Deploy an independent validation agent before any mutation is committed to client systems.
Ready to deploy production-grade multi-agent autonomous systems in your enterprise? Reach out to our engineering team at Binary Froster Solutions.
Ready to orchestrate autonomous agents?
Binary Froster builds resilient multi-agent AI systems. Let's discuss your project.
Get a Free Consultation


